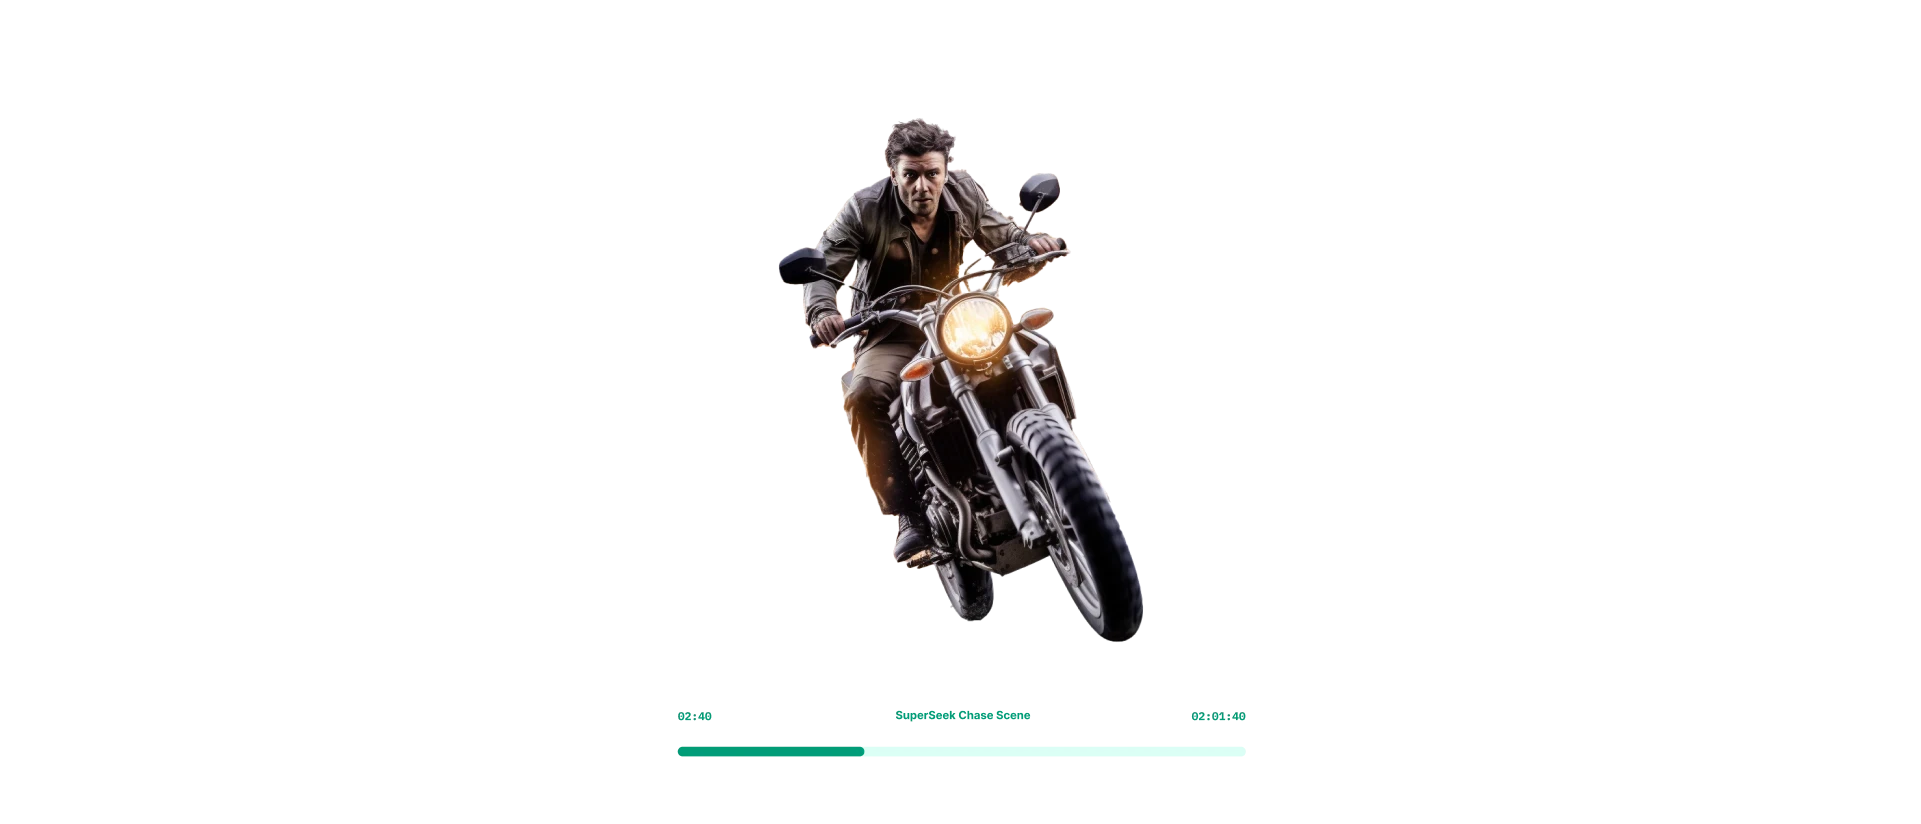
Digital video fingerprinting using Machine Learning
Sriram Hemanth Kumar
2 Months
C++
OpenCV
You Only Look Once
Abstract
Efficient and accurate object detection has been an important topic in the advancement of computer vision systems.
With the advent of machine learning techniques, the accuracy for object detection has increased drastically.
A major challenge in many of the object detection systems is the dependency on other computer vision techniques for helping the machine learning based approach, which leads to slow and non-optimal performance.
The project aims to incorporate state-of-the-art technique for object detection with the goal of achieving high accuracy at faster rate.
Problem Statement
Generally, in video streaming platforms, seeking a video for a specific scene is time-bounded and tiring, with the help of digital video fingerprinting it is made possible to access the specific keyframe with the given.
Why Video fingerprinting?
Mainstream video-sharing platforms can make use of this system for seeking to a particular scene.
It can also be implemented in real life is in automobile vision! As a vehicle travels through a street, the car will be able to quickly identify the vehicle around it, with other sensors to detect how far away that vehicle, the car is able to take the necessary action to stop or avoid the cyclist or other cars or objects to avoid a collision.
Introduction
Objective
To extract the frames from the stream, detect objects, and bind the context with the respective timestamp.
Existing approach
Demands human intervention and is time-consuming.
Current approach
Faster and accurate results.
Proposed Solution
Extracts frame
Detects objects in the scene
Assign timestamp to detected context
Challenges
Object models are heavy
Requires high-end GPU for faster processing
Training models are time-consuming
Not as accurate as classifying by hand
Literature Survey
Faster R-CNN: Towards Real-Time Object Detection with Region Proposal Networks
Authors: Yijun Xiao, Kyunghyun Cho
Year of Publication: 2015
Published in: Neural Information Processing Systems Conference.
Learnings:
A Loss Function for Learning Region Proposals
Optimization
Sharing Convolutional Features for Region Proposal and Object Detection
Generalizes better when training size is limited.
Performs better when number of classes is large, training size is small, and when the number of convolutional layers is set to two or three.
Limitations: it struggles with small objects within the image, for example, it might have difficulties in detecting a flock of birds. This is due to the spatial constraints of the algorithm.
Proposed Work
Compared to other region proposal classification networks (fast RCNN) which perform detection on various region proposals and thus end up performing prediction multiple times for various regions in a image, Yolo architecture is more like FCNN (fully convolutional neural network) and passes the image (nxn) once through the FCNN and output is (mxm) prediction.
This model has several advantages over classifier-based systems. It looks at the whole image at test time so its predictions are informed by global context in the image. It also makes predictions with a single network evaluation unlike systems like R-CNN which require thousands for a single image. This makes it extremely fast, more than 1000x faster than R-CNN and 100x faster than Fast R-CNN.
Architecture
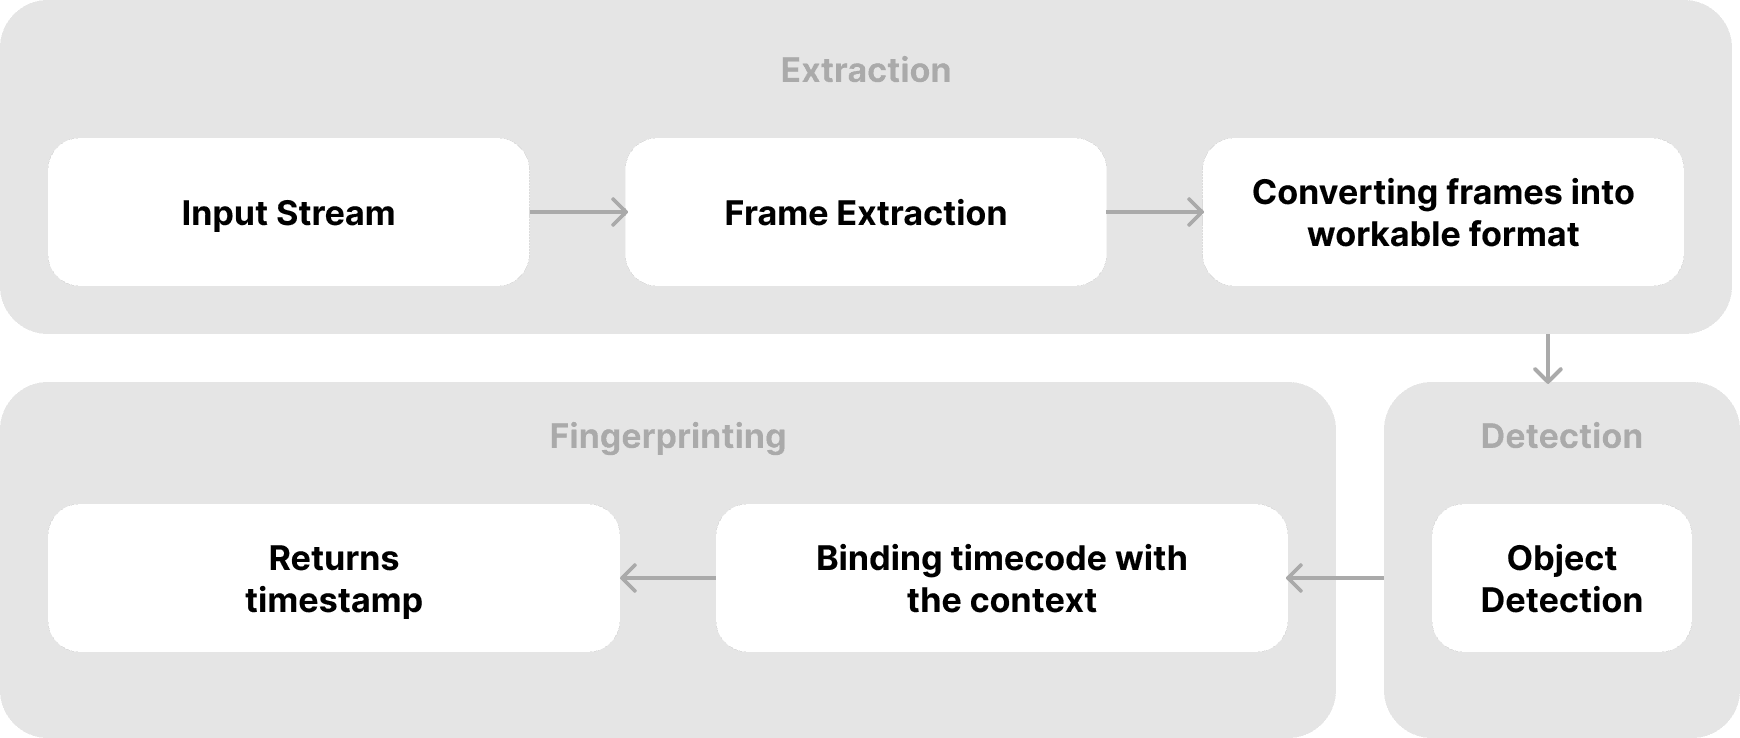
Module Implementation
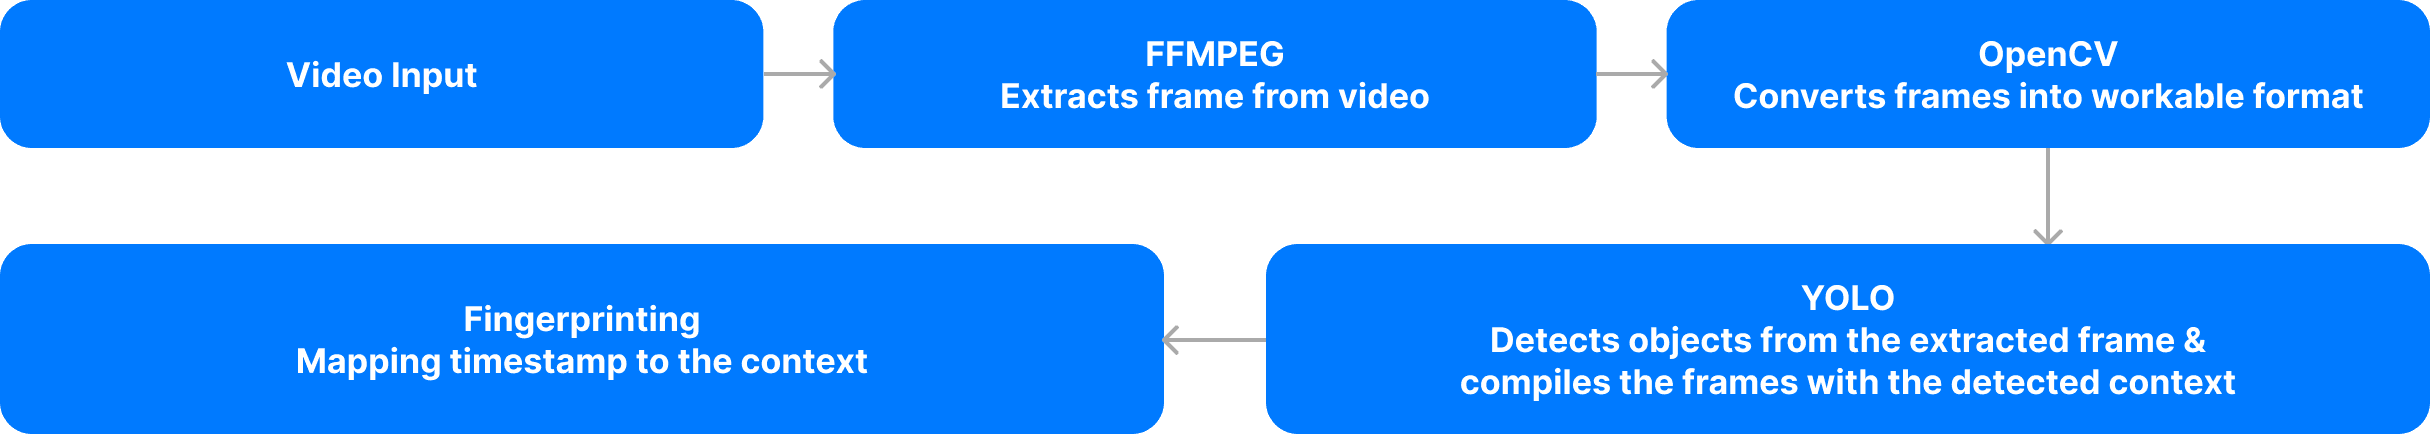
How It Works
Input VIdeo
FFMPEG is a leading multimedia framework able to decode, encode, transcode, mux, demux, stream, filter and play pretty anything that humans and machines have created
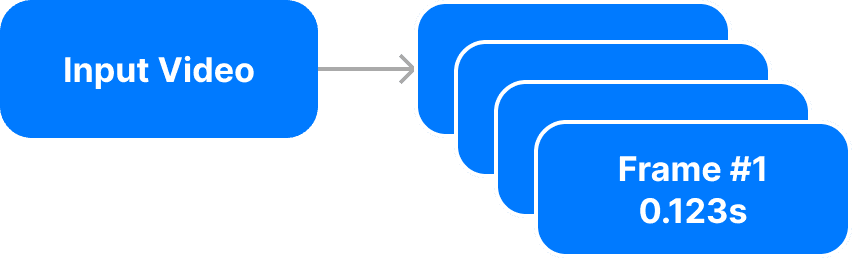
Extracting Frames
Converting frames into workable format
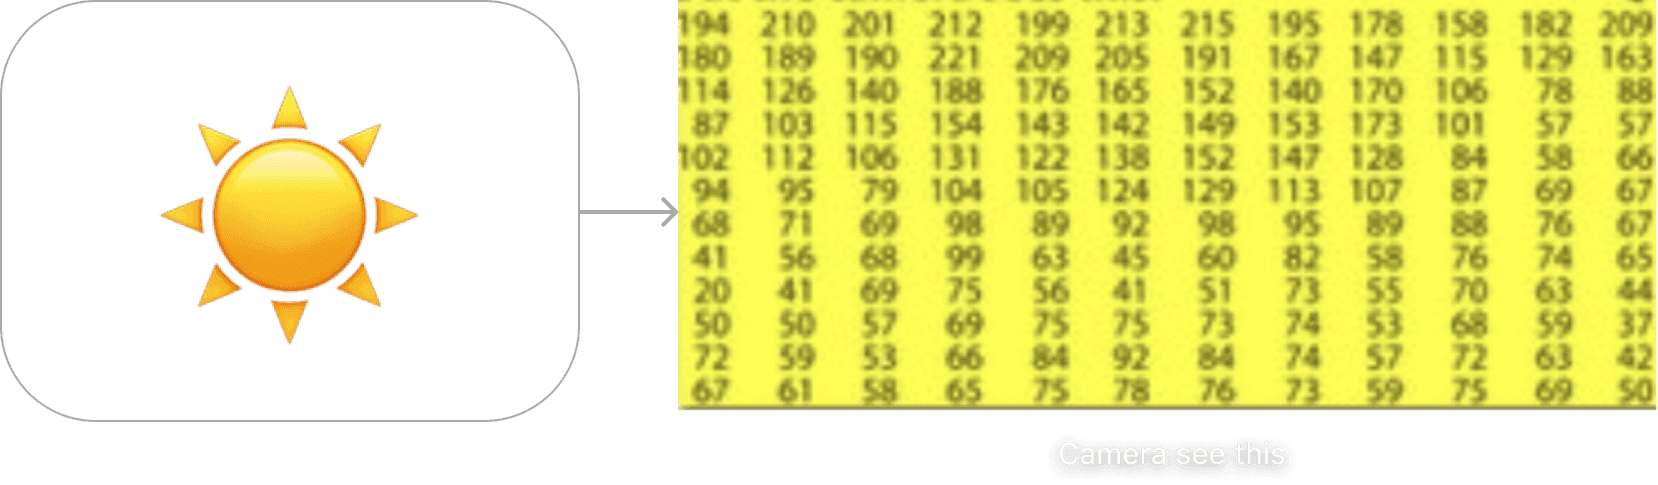
For example in the above image you can see that the mirror of the car is nothing more than a matrix containing all the intensity values of the pixel points. How we get and store the pixels values may vary according to our needs, but in the end all images inside a computer world may be reduced to numerical matrices and other information describing the matrix itself. OpenCV is a computer vision library whose main focus is to process and manipulate this information.
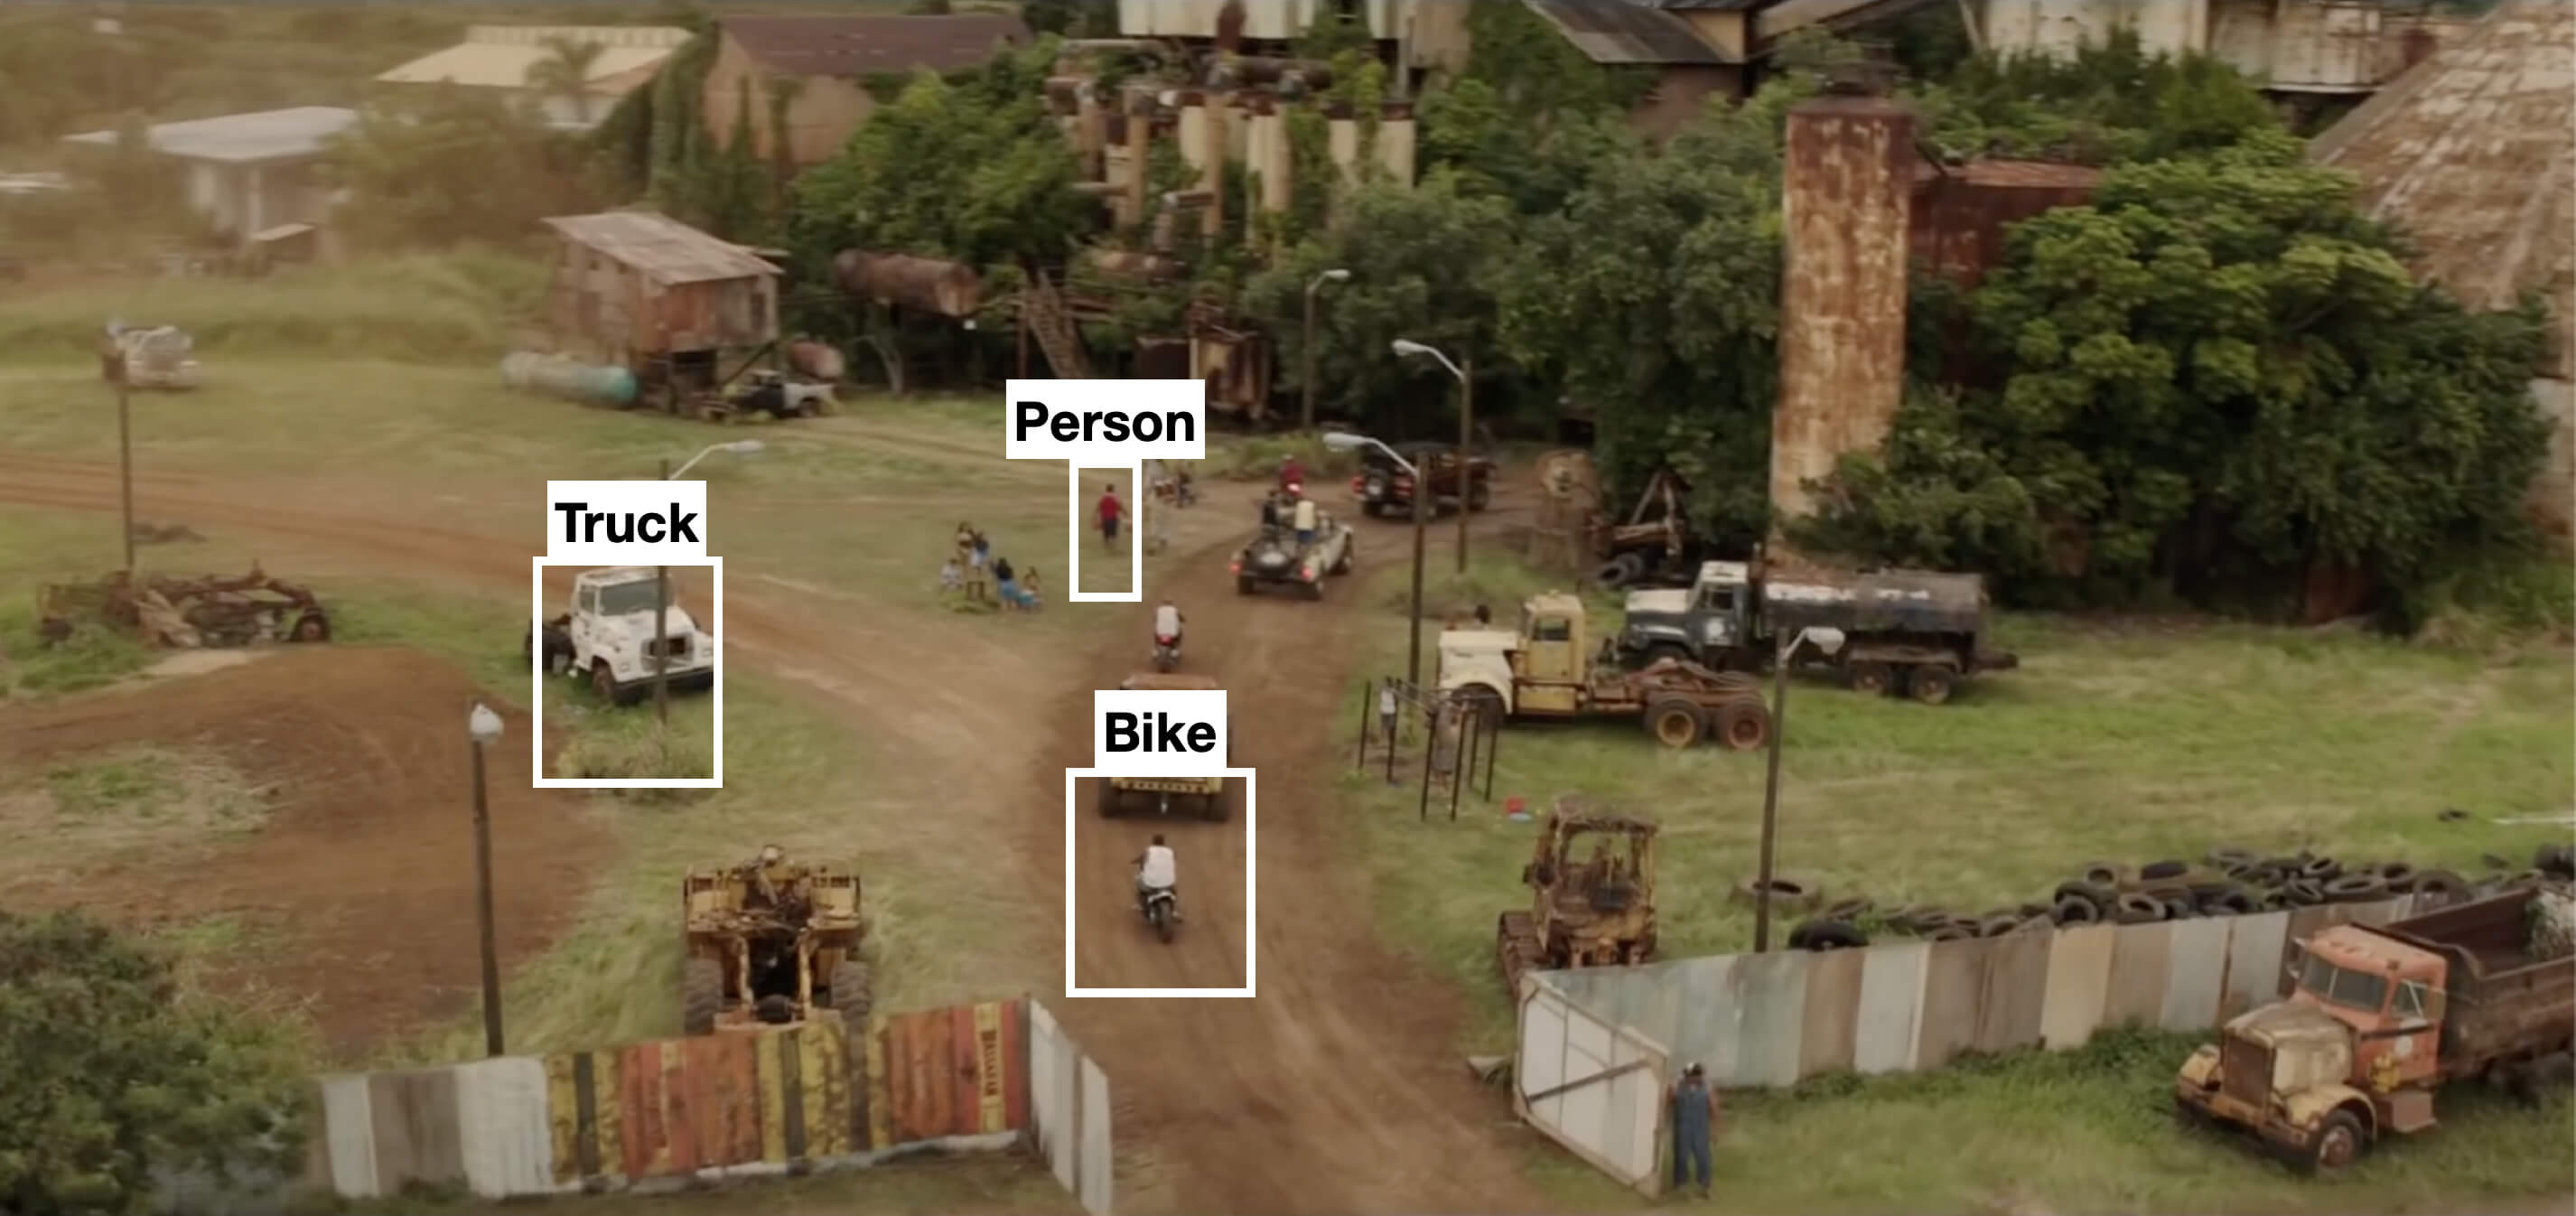
Detecting objects from the extracted frame
Video Fingerprinting
Conlusion
Successfully identified objects in the frames extracted from the video and timestamp is bound to the objects .
We found that DNN architectures are capable of learning powerful features from weakly-labelled data that far surpass feature-based methods in performance .
Future Work
The system can detect not only the objects but categorizes the scene, which enables the user to search a scene and curator to categorize with minimum effort at faster rate.
References
O.S. Amosov, S.G. Amosova (2019) The Neural Network Method for Detection and Recognition of Moving Objects in Trajectory Tracking Tasks according to the Video Stream in 2019 26th Saint Petersburg International Conference on Integrated Navigation Systems (ICINS)
R. Cucchiara, C. Grana, M. Piccardi, A. Prati(2003) ‘Detecting moving objects, ghosts, and shadows in video streams’ in IEEE Transactions on Pattern Analysis and Machine Intelligence, Volume: 25 , Issue 10.
Zhong-Qiu Zhao, Peng Zheng, Shou-tao Xu, Xindong Wu(2019) ‘Object Detection With Deep Learning’ in IEEE Journal, Volume 7, Issue 10.